AI models
LLM workflows, retrieval, evaluation, tool use, and private-model planning when the project needs more control.
Claude / OpenAI / Gemini / open-model evaluation / model routing / RAG / evals / function calling
Analytics only if you accept. Privacy
AI infrastructure, software and public code
Below are the platforms, AI systems, cloud patterns and public repositories behind the work.
JarvisNano, Verrow and Kintunnel have public source linked from their case studies. Other work is documented through its architecture, implementation and available product demonstrations.
Read the codeWrite-ups of what each system does, how it is built and what it changed.
View the work
In short
AI infrastructure and model tooling from a Fort Lauderdale studio: builds on Claude, OpenAI and Gemini models and self-hosted open-weight models, connected with retrieval and MCP servers, and deployed behind server-side token brokers. Some of the source is public on GitHub.
How it runs
Example run
Stack
LLM workflows, retrieval, evaluation, tool use, and private-model planning when the project needs more control.
Claude / OpenAI / Gemini / open-model evaluation / model routing / RAG / evals / function calling
Human-supervised agent systems that can research, code, operate tools, and keep context across real work sessions.
Claude Code / MCP servers / JarvisNano / browser automation / GitHub tools / approval gates
Production web and mobile software with performance budgets, load testing where it matters, and agreed deadlines.
React 18.3 / TypeScript 5.9 / Vite 8 / Vite+ / Next.js / Node / FastAPI / Phoenix / Flutter
Operational systems that connect CRMs, inboxes, forms, payments, documents, and internal dashboards.
PostgreSQL / Supabase / Redis / GoHighLevel / HubSpot / Stripe / n8n / Make / Zapier / webhooks
Deployments designed around portability, observability, security, and the right amount of managed service.
Docker / Traefik / GitHub Actions / Dokploy / private container registry / Vercel / AWS / S3/MinIO / hybrid cloud
Experimental systems where agents meet devices, voice, video, robotics, and real-world inputs.
agent control loops / embedded AI prototypes / ESP32 / voice agents / video understanding / WebRTC / WebSockets
How this helps clients
FAQ
Claude, OpenAI and Google Gemini models (including the Gemini Live API behind our JARVIS voice assistant), and open-weight models we can host ourselves. We choose the model by task, cost and speed, and connect it to your data through retrieval (RAG) and tools (MCP) so it answers from your records.
Yes. Model Context Protocol (MCP) servers give AI assistants controlled access to tools, APIs and internal data, so an agent can look up a record, start a workflow or filter a view. Our JarvisNano prototype calls tools through our JarvisMCP gateway.
Yes. When data residency, cost at volume or speed call for it, we run open-weight models on your cloud or your own servers. When a hosted model is the better choice, we call it through a server-side broker so keys never reach the browser.
Retrieval-augmented generation (RAG) makes an AI answer from your own documents and data, which reduces made-up answers and keeps them current. We build the whole pipeline (ingestion, chunking, embeddings, vector search and re-ranking) and connect it to assistants, search and internal tools.
Keys stay on the server behind short-lived token brokers, model calls run behind rate limits and test suites, and agent actions are limited to the MCP tools we allow. We test model behavior before release; our public DRQ Benchmark project shows how.
Work
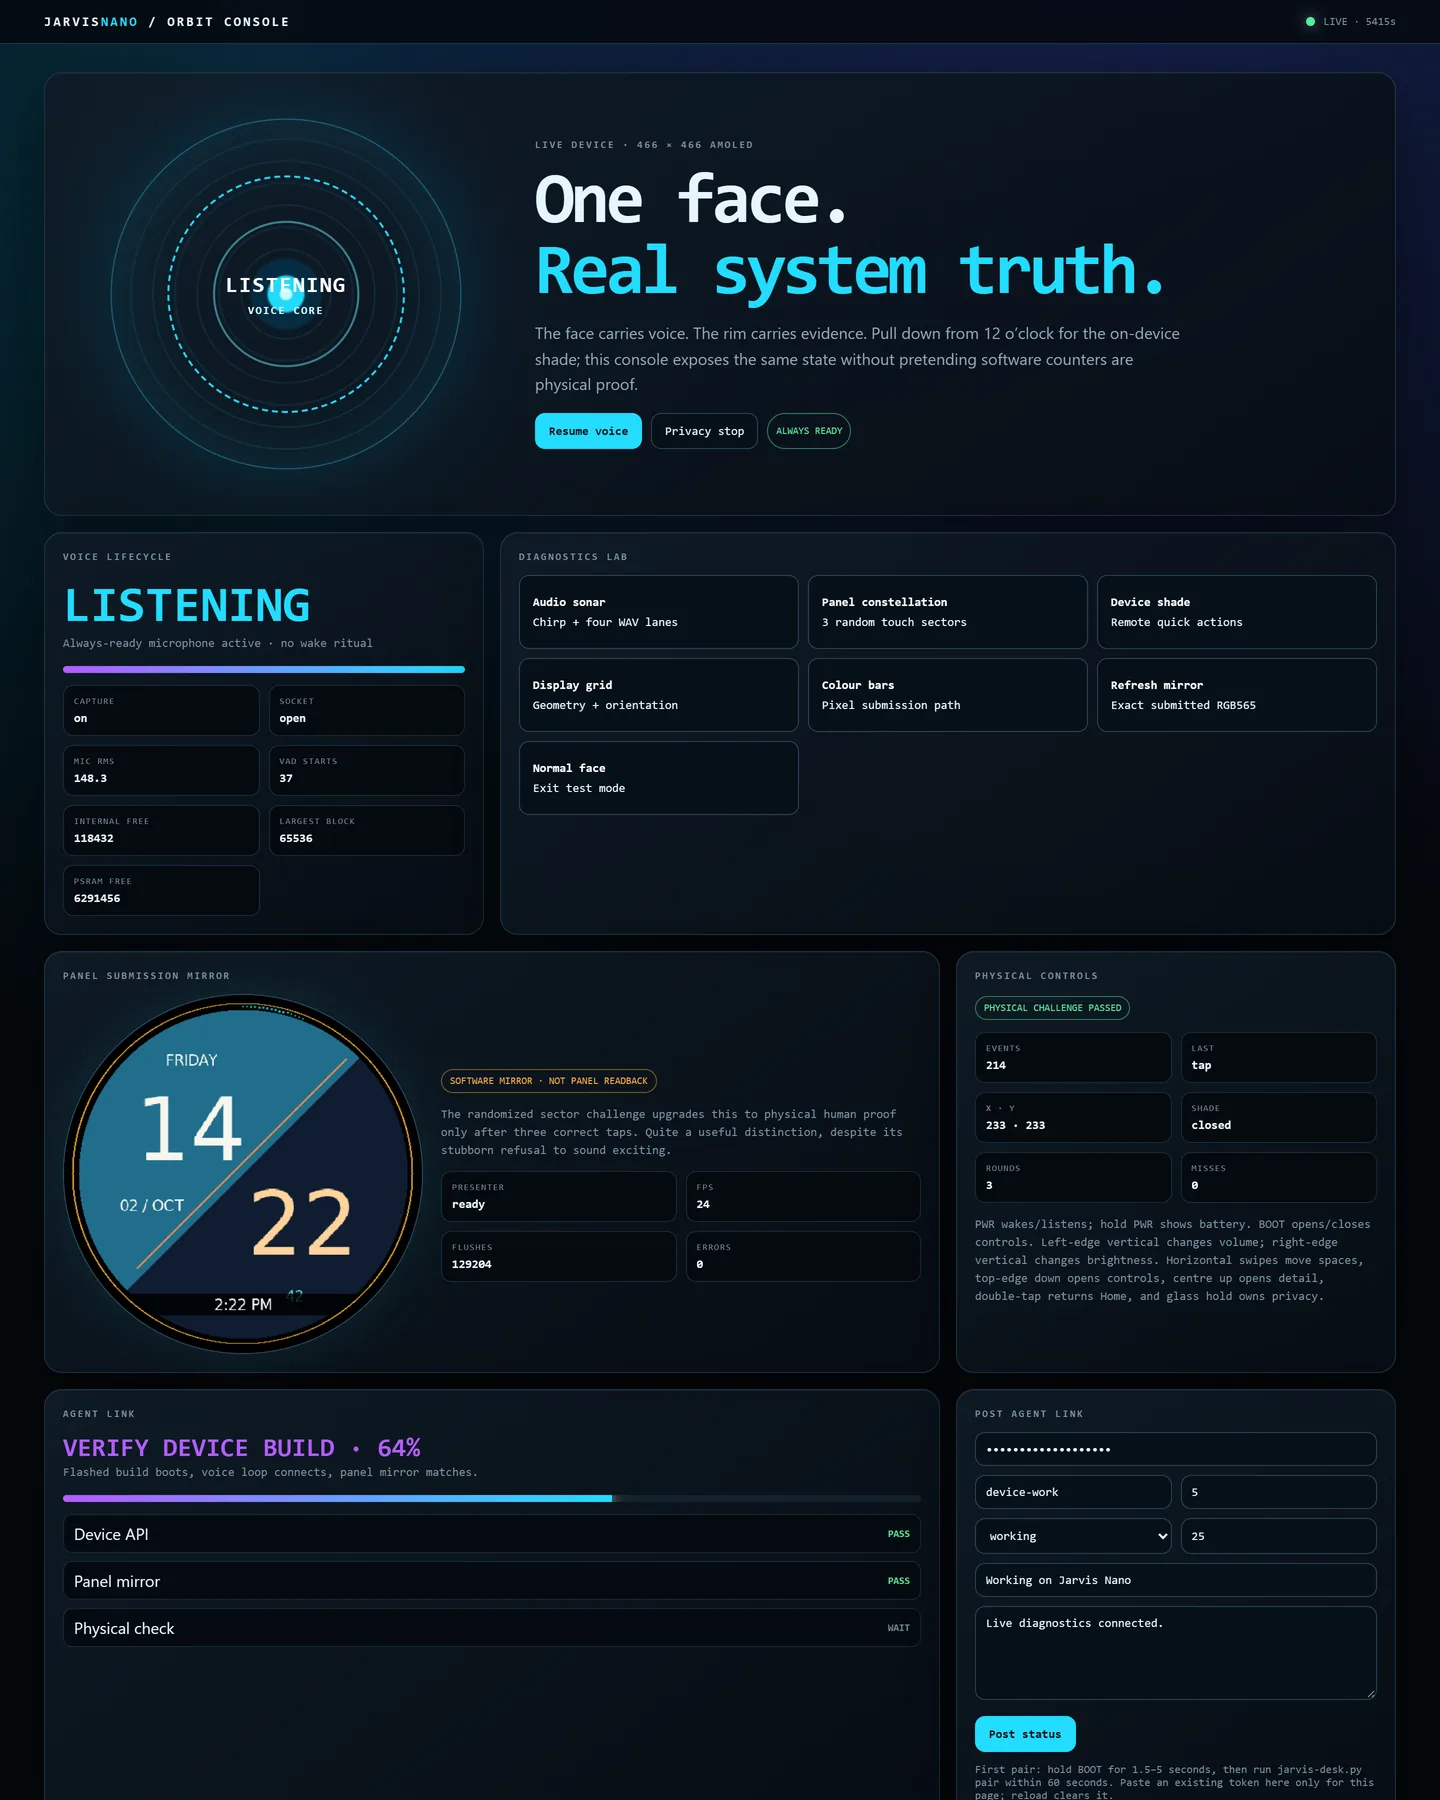
An open-source embedded AI project with C/C++ firmware on the Waveshare ESP32-S3 Touch AMOLED 1.75C and hardware-first prototyping to explore assistants that run on a device. A Kotlin Android app is the optional companion.
Read the case studyEvery change on this page went through the same pipeline: a board item becomes an agent working in its own isolated copy of the code, then a deterministic gate, then a review by a model from a different vendor, and only then does it land.
Read the case study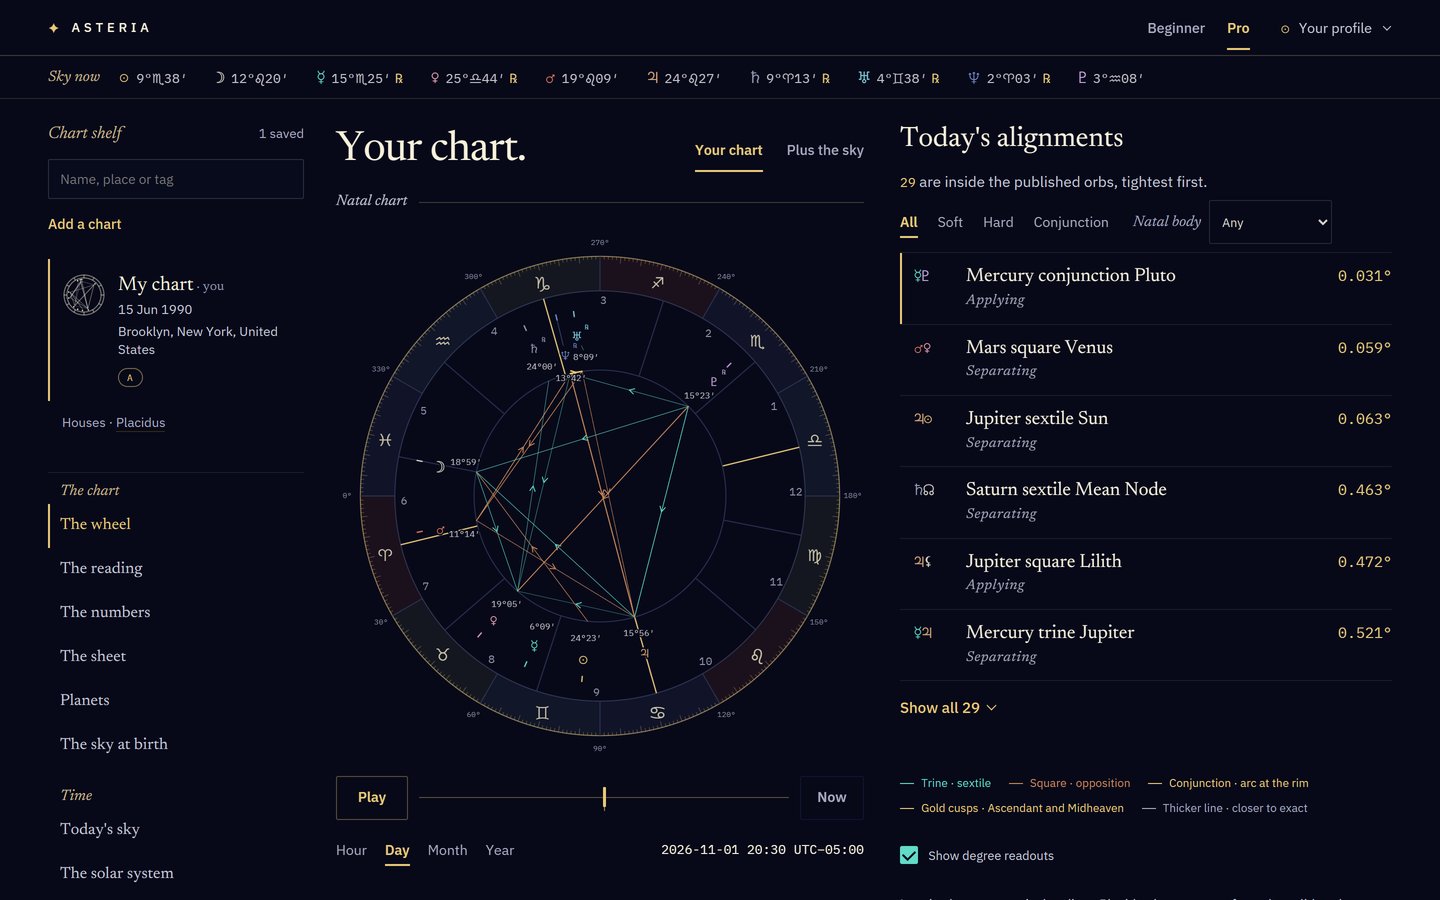
Asteria explains a person's birth chart in plain language and keeps calculated fact visibly separate from interpretation. A Rust calculation engine does the astronomy; a React client makes it readable for complete beginners.
Read the case studyHow we work
The same five gates for our own products and for yours. Nothing reaches your customers on the strength of a demo.
Every change starts in a separate copy of the code, so work in progress never touches what is live.
git worktree add .worktrees/your-changeAgents write and test code beside us. They hold no passwords: every call they make goes through our gateway, which checks it and logs it.
agent → gateway → policy · audit · callTests, before-and-after screenshots of the running app, then independent reviewers. It does not move on until no serious finding is left.
review: 0 high · 0 medium → passThe pipeline builds and deploys. Then we check the running service itself, not just a green build.
replicas 1/1 · image sha matches · health 200Each integration we run is tested against its provider every night, so a changed API is caught before your team notices.
nightly: each integration vs its provider